


- Site Reliability Engineering (SRE)
Keep Your Systems Fast, Available, and Resilient

Reliability by Design. Efficiency by Default.
AIT helps you build and maintain highly reliable, scalable, and observable systems using Site Reliability Engineering principles. From SLAs and alerting to automated rollbacks and error budgets, we help you move fast without breaking things.
Why This Service Matters
As systems grow more complex, availability becomes harder to manage. Without structured SRE practices, teams end up firefighting outages, struggling with noisy alerts, and deploying with fear. We bring discipline, automation, and metrics to your operations.
What Sets Us Apart


SLO-Driven Culture
We design reliability around business goals.
Incident Readiness
From runbooks to blameless postmortems.
Observability-First
Metrics, traces, and logs—all unified.
Automation-Obsessed
We reduce toil with smart tooling and CI/CD.

A Common Customer Challenge
A consumer fintech app is experiencing frequent outages during peak hours, especially around loan disbursements and KYC verification. Their developers are handling ops ad hoc, with no defined SLAs, runbooks, or structured on-call practices.
- No error budget policies to prioritize reliability over feature velocity
- Monitoring tools are siloed and lack real-time alerting
- Postmortems are informal, with no root cause tracking
- Incident response is manual, with high MTTR (Mean Time to Recovery)
- No automated rollbacks, health checks, or circuit breakers in place
Our Solution
AIT introduces SRE practices including SLO definition, incident workflows, monitoring dashboards, and chaos engineering simulations. We deploy observability tools, implement CI/CD safety checks, and build a culture of proactive reliability engineering.

Services Included
- SLO & Error Budget Definition
- Monitoring & Observability Architecture
- Incident Management & Runbook Development
- Alerting Strategy & On-Call Optimization
- Reliability Reviews & Chaos Testing
- Automation of Recovery & Rollback Systems
Technologies & Tools

- Monitoring & Observability
- Prometheus
- Grafana
- Datadog
- New Relic
- Logging, Tracing & Telemetry
- ELK Stack
- OpenTelemetry
- Jaeger
- DMS
- Incident Management
- PagerDuty
- Opsgenie
- VictorOps
- Container Orchestration & Service Mesh
- Kubernetes
- Istio
- Envoy
- Helm
- IaC & CI/CD
- Terraform
- ArgoCD
- Jenkins
A Case Study

Client
Fintech Startup (Southeast Asia)
Challenge
Frequent outages, slow recovery, and no structured reliability practices
Solution
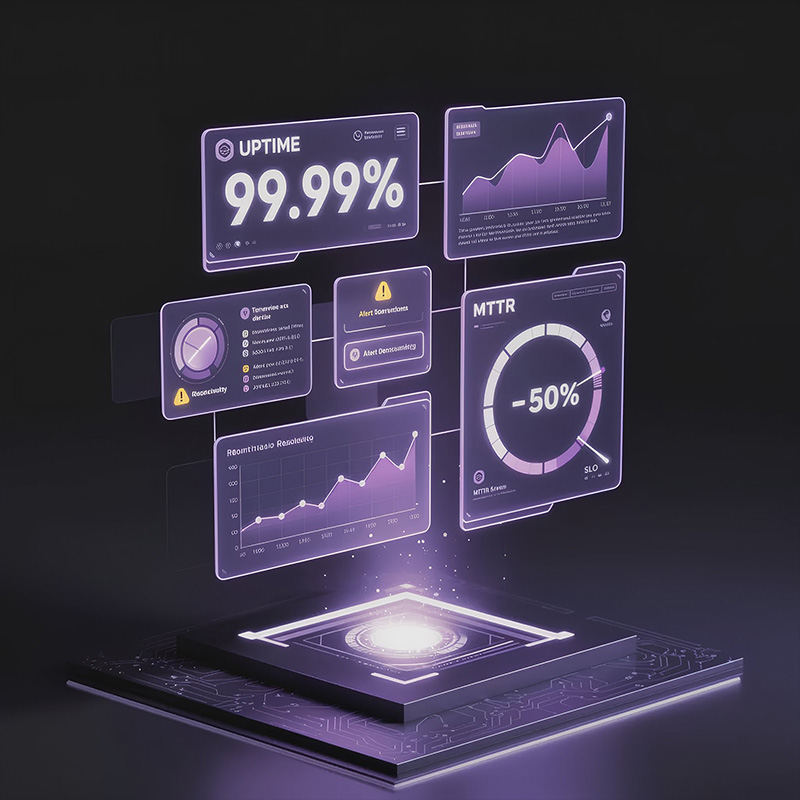
AIT implemented full-stack observability, incident response processes, and error budget tracking. Uptime improved to 99.99%, and mean time to resolve dropped by 50%.
TESTIMONIAL
“AIT helped us stop reacting and start engineering for reliability. Their SRE mindset changed the way we ship—and sleep.”
Ready to Build Systems That Don’t Break Under Pressure?
Ready to Build Systems That Don’t Break Under Pressure?
Book a Reliability Audit with Our SRE Specialists Today.